Skip to content
santoshkandula.dev
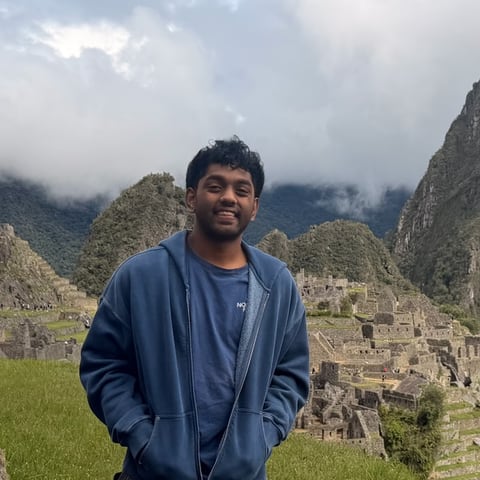
Santosh Kandula at Machu Picchu, Peru

Applied ML + AI

Santosh Kandula

Applied ML engineer building retrieval and vision systems. I publish the metrics that don't flatter the project.

B.S. Computer Science, UNC Chapel Hill · Graduating May 2027

Featured work

RAG + evaluation platform

SEC-RAG-Eval

0.44 → 0.64recall@5 on FinanceBench-150

Audited its own benchmark: the identical retrieval scores 0.09, 0.64, or 0.81 depending only on how a hit is graded.

  • FastAPI
  • PostgreSQL / pgvector
  • text-embedding-3-large
  • Claude Haiku 4.5
  • GCP Cloud Run

Player tracking + play retrieval

hoopvec

0.301 → 0.525HOTA on SportsMOT basketball-val

Traced the cost of tracking analytics to one stage: ID-switches dropped play-retrieval recall@1 from 0.99 to 0.68, and to 0.27 under measured re-ID error.

  • PyTorch
  • Ultralytics YOLOv8
  • ByteTrack
  • BoT-SORT
  • FAISS

Also

NBA playoff bracket prediction

Predicts playoff series winners from regular-season team stats, chained into full brackets.

85.3% accuracy on held-out playoff matchups across four seasons — a Keras network selected over decision-tree and random-forest baselines on measured accuracy, not depth. Honest limitation: that is per-matchup accuracy, and the model ignores home-court advantage.

Public repo

Wildfire risk classifier

Rare-event risk scoring over 10,000 California parcels (IRMII / UNC).

Parcel-level features fused from FEMA hazard layers and carrier exposure data lifted PR-AUC from a 0.61 logistic baseline to 0.76, then scored into calibrated tiers that flagged $27.5M of high-risk insured value. Naming the baseline is the point: measured against the simplest thing that could work, 0.61 → 0.76 is a claim someone can check.

Coursework · no public repo

Experience

Machine Learning Intern · Duke Energy

May 2026 – Aug 2026

  • Gave schedulers a median 3 weeks' warning of project slips vs. about 7 days under manual tracking on the same unseen projects, by building and serving the team's first XGBoost slip model.
  • Raised the share of slips caught from 0.73 to 0.83 recall at the deployed 0.80 precision by adding scheduler interviews, grouped into 9 issue patterns by BERTopic with k-means clustering.
  • Deployed the model on-prem to 25 schedulers on 12 projects, who used it 3.5 sessions a week, owning the backend that filtered Primavera P6 data into PostgreSQL with AWS Bedrock.

Software Engineer Intern · Duke Energy

May 2025 – Aug 2025

  • Turned a 3-week manual inventory of a storm-restock yard, the stock line crews draw on during outages, into a 5-day drone-scan pipeline by training a Mask R-CNN to identify each item from overhead images.
  • Lifted F1 on unseen yard areas from 0.71 to 0.86 by tracing the model's errors to catalog-only training, which failed in sunlight and at drone angles, and writing an OpenCV script to polygon-label field images.
  • Wrote the pipeline whose item counts matched a manual audit 81.5% of the time in a full-yard trial with a human-operated drone, tiling each survey, running detection and rolling counts into the inventory records.

Analyst · UNC Baseball Analytics

Sep 2023 – May 2024

  • Replaced the staff's manual spray charts with a model of where each opposing hitter puts the ball in play, and expected runs allowed fell from 5.1 to 4.4 per game over the remaining 50 games vs. the first 10.
  • Cut the miss on each hitter's average landing spot from 7.3 ft to 2.8 ft on unseen games by choosing contact quality and direction over batting average by zone as inputs to scikit-learn gradient-boosted trees.
  • Served 48 coaches, players, and staff a Flask Plotly scouting dashboard backed by the spray model, adapting an open-source TrackMan ETL into the program's first in-house PostgreSQL pipeline to replace a paid vendor.

Researcher · Duke University

May 2022 – Aug 2022

  • Beat manual field calls at sorting incoming lightning strikes into three types, 0.84 vs. 0.69 per-class precision on the same test set, with a TensorFlow Decision Forests classifier that automated first-pass sorting.
  • Shortened strike classification from next day to a median of 34 minutes after arrival by moving the classifier off daily batch uploads and onto a FastAPI endpoint the lab's field stations posted to.
  • Put the classifier into daily lab use, where 100+ field analysts triaged incoming strikes with it before human review, and all 14 researchers adopted the waveform preprocessing pipeline built for it as their standard.

Internal and corporate roles — no public repositories.

About

I'm a CS senior at UNC Chapel Hill. Two projects define what I work on: a live RAG service over SEC filings that publishes its real recall@5 — 0.44 to start, 0.64 after the work — instead of the number a demo would claim, and a multi-object tracker over broadcast video evaluated with HOTA rather than raw detection accuracy. Both are built around the same idea: the evaluation is the hard part, and a system you've only measured where it succeeds is a system you don't understand. I also spend two summers a year doing applied ML inside Duke Energy, which is where I learned what production constraints actually look like.

I'm looking for applied ML roles starting summer 2027 — retrieval and evaluation infrastructure, ML platform, perception, or applied AI product. Open to San Francisco, New York, Seattle, and remote.
Contact

Best reached by email. The SEC-RAG-Eval demo is live if you'd rather poke at the work first.